Ask for judgments with probabilities
A lot of what a program asks a model is really a decision: which category a message belongs to, where a report falls on a scale, whether something happened or not. For those, you rarely want a paragraph back, and you often need to know how sure the answer is, so that you can act on the confident ones and send the doubtful ones to a person. A model’s own words can’t tell you that. “I’m fairly confident” is more writing, not a measurement.
In LM15, a question like this is called a judgment: you declare the answers you accept, and you get back the pick, plus a probability for every option when the model can measure one. Each probability comes labelled with how it was measured, so a number never changes meaning when you change model.
On this page, we’ll describe three judgments and ask them of TypeSafe’s Jev, a model built to answer this kind of question with probabilities. We’ll read what comes back, then send exactly the same request to an ordinary chat model and see what changes. Next, we’ll ask LM15 to refuse rather than answer without numbers, and judge several notes in a row, side by side. We’ll finish with a different kind of question: where, in a photo, the animal is.
To run the examples, you’ll need a TypeSafe API key in TYPESAFE_API_KEY, and
for one section an Anthropic key, set up as in
Make your first request. Each example
builds on the ones before it, like cells in a notebook.
Describe the answers you accept
Section titled “Describe the answers you accept”The examples in these guides follow one small program: an assistant for a wildlife research station. Observers write short field notes, and the station wants three facts from each one: which animal the note is mainly about, how sure the observer was of the species, and whether an animal was hurt. Each fact is a judgment:
from lm15 import (Config, LMRouter, Message, Request,                  choice, judgments, score, yes_no)
answers = judgments(    animal=choice("Which animal is the note mainly about?",                  ["badger", "fox", "owl", "hare", "deer"]),    certainty=score("How sure is the observer of the species?",                    ["guess", "probable", "confident"]),    hurt=yes_no("Does the note report a hurt animal?"),)
There are three kinds, one for each kind of question:
choicepicks one of a set of options, here five animals. The order doesn’t matter.scoreplaces the answer on ordered levels, from the lowest to the highest. Here,guessis belowprobable, which is belowconfident, and that order will matter later.yes_noanswers yes or no.
Each one takes the question in plain words, which the model reads, and
judgments gathers them into one description of the answer. That description
is an ordinary JSON schema, the same thing
Get structured output uses; the three helpers
only save you writing it by hand. So far nothing has been sent.
Ask Jev
Section titled “Ask Jev”Here’s the note from the stream camera, sent to Jev with the answers above.
probabilities="if_available" asks for the numbers wherever the model can
measure them:
note = ("Checked the stream camera this morning. Three\n"        "badgers came through overnight, one of them limping.\n"        "A fox passed later, just before dawn.")
router = LMRouter()reply = router.complete(Request( model="jev-latest", messages=[Message.user(note)], config=Config(response_format=answers, probabilities="if_available"),))print(reply.data)print(reply.probabilities)print(reply.method){'animal': 'badger', 'certainty': 2, 'hurt': True}
{'animal': {'badger': 1.0, 'fox': 0.0, 'owl': 0.0, 'hare': 0.0, 'deer': 0.0}, 'certainty': {'0': 0.0, '1': 0.05, '2': 0.95}, 'hurt': {'true': 0.98, 'false': 0.020000000000000018}}
provider_classificationThree lines, three things to read:
datais the pick, one entry per judgment:badger, level2, andTrue. Ascoreanswers with the number of its level, counting from 0, so2isconfident. It’s a plain dictionary, ready to store.probabilitiesis how sure Jev was, one set of numbers per judgment, over exactly the options you declared. Jev put everything onbadger, which fits: the note names badgers first and the fox only in passing. For the certainty it put 0.95 onconfidentand 0.05 onprobable. For yes or no, Jev measures one number, the chance of “yes”; “no” is 1 minus it, which is why it prints as0.020000000000000018instead of0.02(a rounding quirk of how computers store decimals, not a second measurement).methodsays how the numbers were measured:provider_classificationmeans the provider’s own model produced them. We’ll come back to why that label matters.
Because certainty is ordered, its numbers can also be summed up as a single
position on the scale, weighting each level by its probability:
print(reply.expected("certainty"))1.95
That’s 0 × 0.0 + 1 × 0.05 + 2 × 0.95: close to the top of a scale that runs
from 0 (guess) to 2 (confident). One number per note is much easier to sort
and compare than three, as we’ll see at the end of the page.
The same request on a chat model
Section titled “The same request on a chat model”Now the same request, with only the model changed, to Anthropic’s small model:
reply = router.complete(Request( model="anthropic:claude-haiku-4-5", messages=[Message.user(note)], config=Config(response_format=answers, probabilities="if_available"),))print(reply.data)print(reply.probabilities)for change in reply.adaptations: print(change.field, change.action){'animal': 'badger', 'certainty': 2, 'hurt': True}
None
config.max_tokens defaulted
config.probabilities droppedThe pick is the same, and still a plain dictionary: the chat model received the
answers as a JSON schema and filled it in. But probabilities is None, and
two lines say why. A chat model writes one answer; it doesn’t report how likely
each option was, so LM15 had nothing to measure. Rather than make numbers up,
it dropped the setting and recorded that it did. (The other line is
unrelated: Anthropic requires a length limit, and LM15 filled in its default;
see Control generation.)
This is the general rule for probabilities in LM15: they are either measured, or absent. Never invented, and never quietly different from what you asked.
When the numbers are the point
Section titled “When the numbers are the point”If your program can’t work without the probabilities, say so with
"required":
reply = router.complete(Request( model="anthropic:claude-haiku-4-5", messages=[Message.user(note)], config=Config(response_format=answers, probabilities="required"),))UnsupportedFeatureError: anthropic: config.probabilities='required' but this wire cannot measure a distribution over the declared keys (it returns a pick only); use 'if_available' or a provider that can (typesafe, or a vLLM/SGLang server that honours logprob_token_ids)
LM15 refuses before sending anything, so the refusal costs nothing, and the
message names the providers that can measure probabilities. Use "required"
whenever a missing number would be a bug, for example when a person only
reviews the answers below some probability.
Many notes, side by side
Section titled “Many notes, side by side”Probabilities pay off when you compare answers. Here are the station’s three notes, judged one after another, printing the animal and the expected certainty for each:
notes = { "stream": note, "barn": ("Around midnight an owl was calling from the old\n" "barn roof, probably a tawny. Two hares in the barn\n" "field at first light."), "deer": ("Dusk, edge of the oak grove. Two deer browsing on\n" "fallen acorns, one small with spots still showing.\n" "Too far to be sure of the species: roe or fallow."),}for name, text in notes.items(): reply = router.complete(Request( model="jev-latest", messages=[Message.user(text)], config=Config(response_format=answers, probabilities="if_available"), )) sure = reply.expected("certainty") print(f"{name:7}{reply.data['animal']:8}{sure:.2f}")stream badger 1.97 barn owl 0.95 deer deer 0.04
Read the last column against the notes’ own words. The stream note just
reports what the camera saw: 1.97, almost fully confident. The barn note
says “probably a tawny”: 0.95, probable. The deer note says “too far to be
sure of the species”: 0.04, a guess. The picks alone would have given 2,
1 and 0; the expected values also show how firmly each level was chosen,
which is what you’d sort by to decide which notes a person should check.
Notice too that the stream note scored 1.95 in the earlier call and 1.97 here. Jev’s numbers vary slightly from one request to the next, so treat the second decimal as noise.
What the numbers mean
Section titled “What the numbers mean”A probability from Jev and one from another method can look identical and
still measure different things. Besides Jev, LM15 can measure probabilities on
a vLLM server (0.29 or later) that reports the likelihood of each answer’s
tokens; there, method is candidate_sequence_likelihood, and
provider_data["coverage"] says how much of the model’s probability landed on
your options at all. Neither method is calibrated on your notes until you
check it against answers you know. That’s why method travels with the
numbers instead of being a setting: when you change model, a 0.8 can’t
silently start to mean something else. Jev’s own confidence score, when it
sends one, is kept unchanged in provider_data["typesafe"].
Jev also reads its input differently from a chat model. It takes exactly one
user message and nothing else: no instructions (system) and no earlier
conversation. LM15 refuses a request that has either, rather than inventing a
way to squeeze them in. Context goes in the message itself, or in the
question’s own words. To give Jev structured input, send
Message.user(data({...})) with a dictionary; Jev reads it as data, and a chat
model receives the same request as JSON text.
Jev can also judge pictures. Put a PNG or JPEG image in the user message, on its own or beside text, and ask your questions about “the image” or “the second image”, as you would ask a chat model. LM15 sends the picture’s bytes, so an image given only by a web address is refused: download it first. TypeSafe still calls images an early feature, so check the answers on pictures whose answers you already know before you rely on them. Pictures for Jev need Python 1.4.0, TypeScript or Rust 1.0.0-rc.9, Go v1.1.0-rc.8, R 1.3.0, or later; Julia’s first release will include them.
Ask where: a bounding box
Section titled “Ask where: a bounding box”Pictures make one more kind of question possible: not what is in a photo,
but where. bounding_box asks for the smallest rectangle around something,
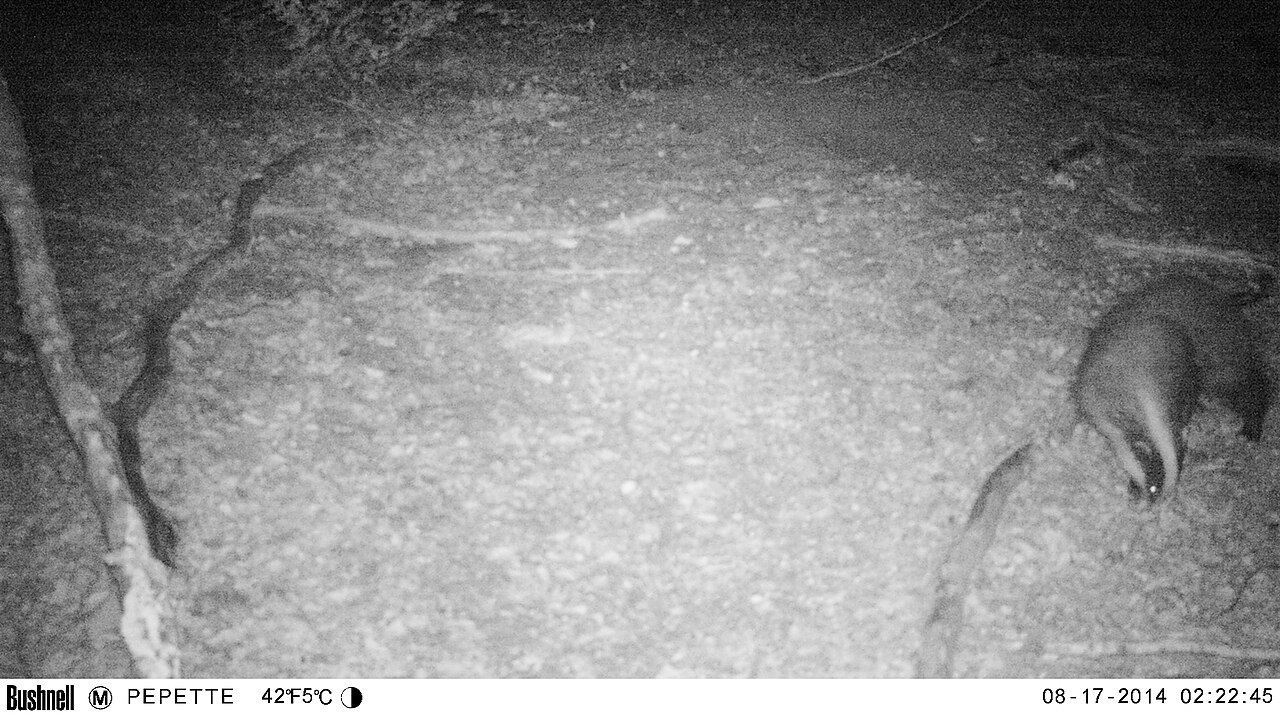
here the badger in the camera-trap photo from
Send images and documents. Save
the photo next to your program first:
from lm15 import bounding_boxfrom lm15.types import image
where = judgments( badger=bounding_box("the badger in the image"), seen=yes_no("Is there a badger in the image?"),)reply = router.complete(Request( model="jev-preview", messages=[Message.user(image(path="badger.jpg"))], config=Config(response_format=where),))print(reply.data){'badger': {'top': 0.38, 'bottom': 0.71, 'left': 0.85, 'right': 0.99}, 'seen': True}The box is four numbers, one per edge. Each is a fraction of the photo,
measured from its top-left corner: top and bottom of its height, left
and right of its width. So the badger sits at the right edge, from 0.85 to
0.99 of the way across and from 0.38 to 0.71 of the way down. Fractions don’t
depend on the photo’s size; to draw the box or cut it out, multiply by the
size in pixels:
width, height = 1280, 718 # the photo's size, in pixelsbox = reply.data["badger"]print(round(box["left"] * width), round(box["top"] * height), round(box["right"] * width), round(box["bottom"] * height))1088 273 1267 510
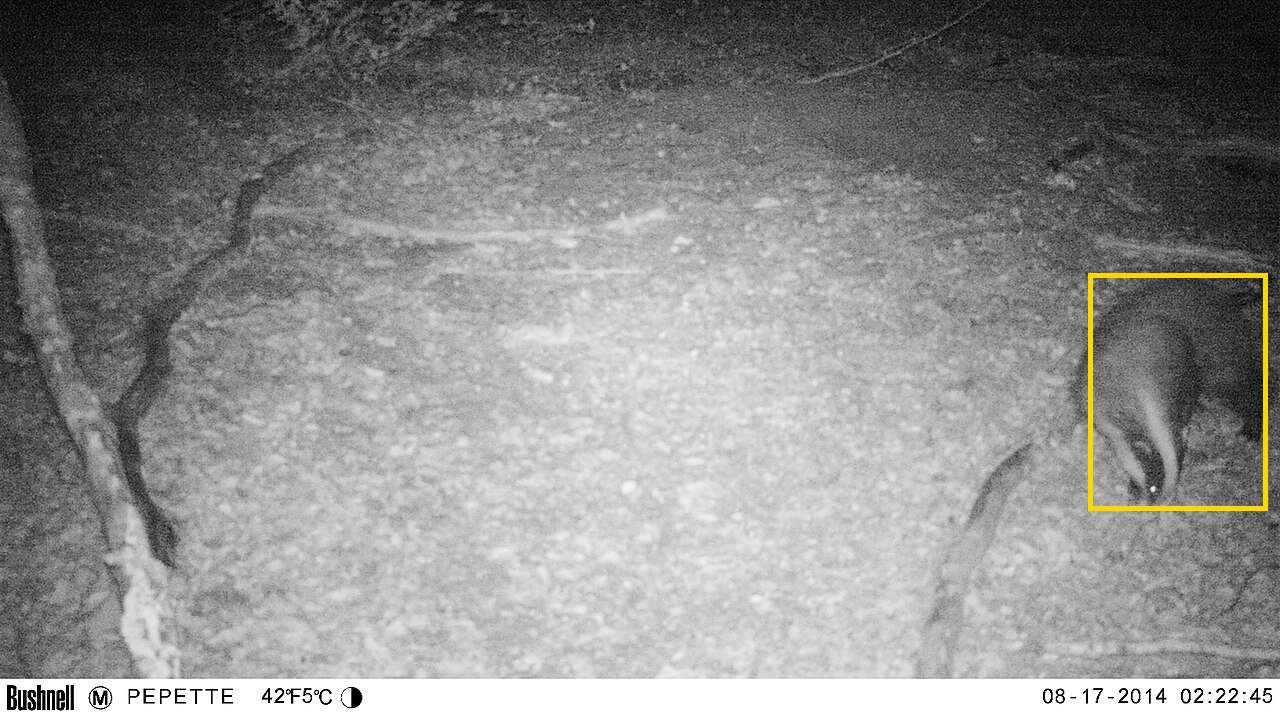
The box Jev gave, drawn on the photo. Photo: “Blaireau au début de la nuit” by peupleloup, Wikimedia Commons, CC BY-SA 2.0; box added.

A box differs from the other three kinds in a few ways:
- It has no probabilities. It isn’t a pick from options you listed, so
there is nothing to spread a probability over:
reply.probabilitiescoversseenonly, and"required"never refuses because of a box. Jev’s own confidence in the box is kept inprovider_data["typesafe"]. - It is always four edges, even in a photo with no badger. That’s why
seenis there: ask a yes-or-no beside the box, and ignore the box when the answer is no. - On TypeSafe, it needs Jev 1.14, which is
jev-previewfor now.jev-latestwas still Jev 1.13 when we wrote this, and answers a bare “Invalid request.”. - On other models, the same request still works: the model writes the four numbers itself. How close they are depends on the model. On a test picture of two shapes, Jev and OpenAI’s GPT-5.6 Luna were within 0.04 of the true edges, Claude Sonnet 4.5 and Gemini 2.5 Flash about 0.15 off, and Claude Haiku 4.5 0.3 to 0.4 off. Check a few boxes you can see before relying on any model.
Boxes need Python 1.5.0, TypeScript or Rust 1.0.0-rc.11, Go v1.1.0-rc.10,
R 1.4.0, or later; Julia’s first release will include them. The helper is
boundingBox in TypeScript and BoundingBox in Go.
Try it yourself
Section titled “Try it yourself”- In
answers, replace thecertaintylevels with just["unsure", "sure"]. Before running it, predict the deer note’s expected certainty: close to 0, close to 1, or in between? - Add a fourth judgment,
young=yes_no("Does the note mention a young animal?"), and run the table again. Which note should answer yes? - Send the table’s requests with
probabilities="required"toanthropic:claude-haiku-4-5. How many requests reach Anthropic?
Answers
- Close to 0 (it was 0.00 when we tried it, on September 24, 2026): “too far
to be sure” points clearly at
unsure. The surprise is the barn note: with no middle level, “probably a tawny” falls tounsuretoo (0.02). The levels you offer shape the answers, so choose them for the decision you’ll make. - The deer note: “one small with spots still showing” is a fawn (0.97 for yes when we tried it). The other two answer no.
- None. The first request is refused before it is sent, so the loop stops
there, with the same
UnsupportedFeatureErroras above.
Judgments are structured output with one addition, the probabilities; for answers that are free-form data rather than choices, see Get structured output. When you judge many notes in a row, some requests will meet a rate limit; see Handle errors and retries. The rules behind this page are in the shared contract: judgments (MAP-14), what Jev reads, pictures for Jev, and bounding boxes.