LM15 overview
Every company that serves language models has its own API, and every programming language has its own libraries for calling them. Each one has its own way to write a request, read an answer, stream it, and call a tool, so moving from one to another means learning the same ideas again. LM15 is one way to do all of that, for many providers, in six languages. You learn it once, and use it everywhere.
This guide will teach you how to use LM15. This page is a quick tour of the parts of a request and a response, with the smallest code that shows each one. Make your first request then goes through them slowly, with real answers, and each page after that adds one ability.
Choose your language, provider, and model at the top left of the page. The code examples follow your choice; the explanations don’t change, because LM15 works the same way in every language and with every provider. Pick the provider your API key belongs to, and a model your account can use.
If you’d rather learn by trying things, the playground lets you
build a request in your browser, send it, and see the code that makes it. If a
coding agent is writing your code, point it to the LM15 skill or to
llms.txt.
The example we’ll build
Section titled “The example we’ll build”Throughout this guide, we build one small program: a field assistant for a wildlife research station. First you ask it a question any naturalist might: what is eating the acorns under the oak trees at night? Over the following pages, it searches the sightings your station has recorded, keeps track of a conversation, identifies an animal in a camera-trap photo, turns observers’ field notes into tidy records, and sorts a whole season of notes at once. Each page adds one ability to the same program.
This page is a quick tour. It names the parts of a request and a response, and shows each one in the smallest amount of code. Don’t worry if not everything makes sense yet: the pages that follow go through each part slowly.
The parts of a request
Section titled “The parts of a request”A request describes what you want. A response records what came back.
Request model which model to ask required messages the conversation so far required system instructions for the whole request optional tools functions the model may ask you to run optional config settings, such as a length limit optional ↓Response message what the model said finish_reason why it stopped usage what the provider countedOnly model and messages are required. Leaving out an optional part isn’t
the same as setting it to zero or switching it off: it means you haven’t asked
for anything, and the provider does what it normally does.
Model and messages
Section titled “Model and messages”Here is the smallest request: a model, and one message from you.
request = Request(
    model="provider:model",
    messages=[Message.user(
        "What might be eating the acorns under our oak trees at "
        "night?"
    )],
)
model names the model you want. With the router, provider:model also
names the provider to contact; the router removes the prefix before passing the
name on. A model name belongs to one provider, so changing providers usually
means changing the model name too.
messages is the conversation, in order. Each message has a role
(user, assistant, tool, or developer) that says who it is from, and one
or more parts. A part is one piece of content: some text, an image, a call to
a tool. To continue a conversation, you send the earlier messages again,
followed by the new one. Keep a conversation shows how.
Nothing is sent yet: a request is just a value. It goes to the provider when you hand it to a client, further down.
System instructions
Section titled “System instructions”system holds instructions for the whole request: who the model should be,
and how to answer. It sits beside the messages, not inside them.
request = Request(
    model="provider:model",
    system=(
        "You are the field assistant for a wildlife research "
        "station. Answer in two sentences."
    ),
    messages=[Message.user(
        "What might be eating the acorns under our oak trees at "
        "night?"
    )],
)tools lists functions the model may ask your program to run. Our
assistant can’t know what your station has recorded, so we offer it a way to
look:
sightings_tool = FunctionTool(
    name="search_sightings",
    description=(
        "Find the station's recorded sightings by species, place or "
        "date."
    ),
    parameters={
        "type": "object",
        "properties": {
            "query": {"type": "string", "description": (
                "One species, place or date, such as 'oak grove' or "
                "'2026-09-18'."
            )},
        },
        "required": ["query"],
    },
)

request = Request(
    model="provider:model",
    system=(
        "You are the field assistant for a wildlife research "
        "station. Answer in two sentences."
    ),
    messages=[Message.user(
        "What might be eating the acorns under our oak trees at "
        "night?"
    )],
    tools=[sightings_tool],
)
A tool has a name, a description the model reads, and a schema describing
its inputs: here, one piece of text called query. It’s a description, not the
function itself: a request holds only data, so what it holds is exactly what the
model receives. The function that does the searching stays in your program.
Offering a tool doesn’t make the model use it. If it wants to, it answers with a tool call instead of text: the name and the input. Your program decides whether to run it, then sends the result back in the next request.
LM15 never runs your functions for you. Call your own functions walks through that loop. Some providers also run tools of their own, such as web search; Use provider tools covers those.
Settings
Section titled “Settings”config holds settings for how to generate the answer. Here, a limit on how
many tokens (pieces of words) the answer may use:
request = Request(
    model="provider:model",
    system=(
        "You are the field assistant for a wildlife research "
        "station. Answer in two sentences."
    ),
    messages=[Message.user(
        "What might be eating the acorns under our oak trees at "
        "night?"
    )],
    tools=[sightings_tool],
    config=Config(max_tokens=1000),
)
Each setting has its own rules. A token limit must be positive, for example.
Other settings include temperature, a required answer format, reasoning effort,
caching, and which tool the model must use. A setting you use still needs a
provider and model that support it. Options that only one provider has go in
config.extensions, under that provider’s own names.
Control generation goes through them.
The response
Section titled “The response”A client sends the request and gives you back a response. Here, the router picks the provider from the model name and reads its API key from the environment (Make your first request sets that up):
router = LMRouter()
response = router.complete(request)
print(response.text)
print(response.finish_reason)  # "stop", "length", "tool_call"…
print(response.usage.input_tokens, response.usage.output_tokens)
The response always has the same three parts, whichever provider answered:
- The message the model wrote. Its text is what you usually want, but a message can also hold tool calls, images, or reasoning.
- The finish reason:
stopwhen the model finished,lengthwhen it hit your limit,tool_callwhen it is waiting for your program to run a tool. - Usage: the tokens the provider counted. A count the provider didn’t report is empty, not zero.
Keep the whole message, not only its text. It can carry data the provider needs to continue the conversation.
Streaming
Section titled “Streaming”A long answer can take a while. Streaming shows it as it’s written. It uses the same request; only the way you receive the answer changes:
stream = ResponseStream(router.stream(request), request)
for text in stream:
    print(text, end="", flush=True)
print()
print(stream.usage.output_tokens, "tokens")
At the end, you get the same complete response as before, with its finish reason and usage. Stream a response explains the pieces a stream is made of.
Putting it together
Section titled “Putting it together”Here is the whole program: model, messages, instructions, a length limit, and the answer streamed as it’s written. It uses the provider and model you chose at the top of the page.
from lm15 import Config, LMRouter, Message, Request, ResponseStream

router = LMRouter()
request = Request(
    model="provider:model",
    system=(
        "You are the field assistant for a wildlife research "
        "station. Answer in two sentences."
    ),
    messages=[Message.user(
        "What might be eating the acorns under our oak trees at "
        "night?"
    )],
    config=Config(max_tokens=1000),
)

stream = ResponseStream(router.stream(request), request)
for text in stream:
    print(text, end="", flush=True)
print()
print(stream.usage.output_tokens, "tokens")
The tool is left out. Once a model can call a tool, your program has to be ready to answer it, and that loop has its own page.
Why a fifteenth standard?
Section titled “Why a fifteenth standard?”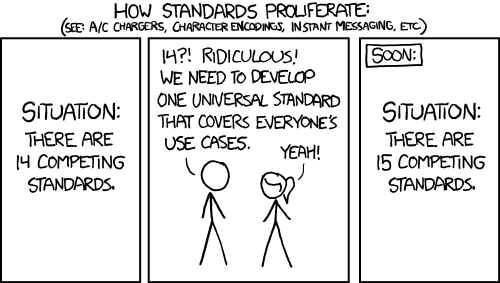
“Standards” by Randall Munroe, XKCD · CC BY-NC 2.5
LM15 is first and foremost a contract: a shared format for requests and responses, to and from language models (large and small), with precise rules for what each field means. It also defines how responses arrive piece by piece when streaming. Each language implementation follows this contract, using the conventions of its language.
An adapter translates an LM15 request into the format a provider accepts, then translates the answer back into an LM15 response. Your application works with the contract; the adapter handles the provider’s details. Learn that one contract, and you can use it across languages and providers without learning a new request and response format each time. Providers still differ in what they can do—the shared format does not erase those differences.
That common meeting point is useful on both sides. Application and framework builders can use it without knowing every provider’s API. Someone connecting a new model service can implement it without knowing every application that will call it.
LM15 began with direct calls to provider APIs, but the contract does not require a remote service. A custom adapter could connect to a model running inside your program through PyTorch or vLLM. It could even connect to a coding agent that runs its own tools and completes several steps before returning an answer. These would be custom integrations, not connections LM15 currently supplies.
The responsibility is the same: read the LM15 request, carry out what it asks, and return an answer that follows the response rules. If the system cannot honor part of the request, report that rather than silently ignore it. Applications can then use the connection through the same contract.
What else you can express
Section titled “What else you can express”LM15 is not limited to the features every provider has in common. Features shared by several providers have common fields; options only one provider has go in extensions, under the provider’s own names. On the response side, provider_data keeps the provider’s original answer beside the shared fields. That separation shows you exactly where your code relies on one provider.
Shared does not mean universal, though: you still need a provider and model that support what you ask. The shared capabilities include streaming, tools, structured output, reasoning, prompt caching, images and documents, and errors and usage. Separate APIs cover files, batches, media generation, video jobs, and realtime sessions.
Next, make your first request: install LM15, set one API key, and send a request in the language you chose.